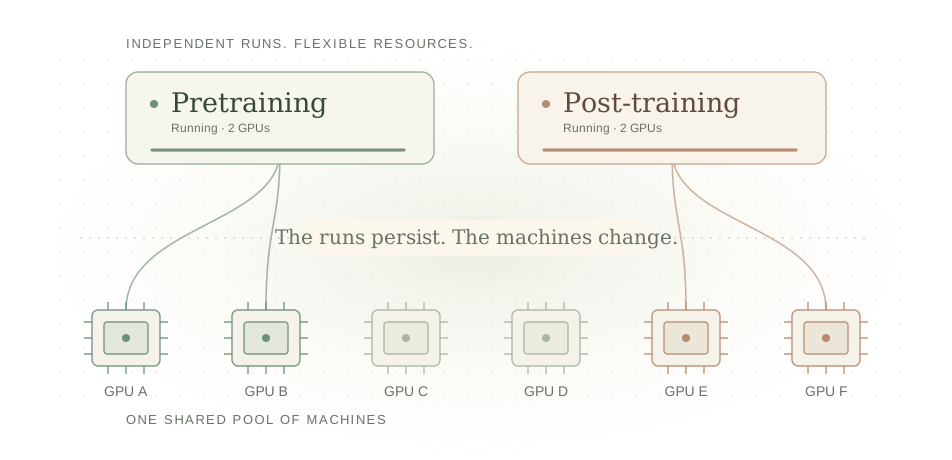
What if a training run could have a life of its own? It could begin on the machines available today, pause when those resources are needed elsewhere, and resume tomorrow on a different allocation. It could grow with new capacity, contract when demand changes, and recover when a machine fails. The work would have continuity, even when its execution does not.
This is the future we want to build: training untethered from its machines. Our long-term goal is to decouple both pretraining and post-training from the hardware that happens to execute them. A run would keep its identity and recoverable state as its placement, size, and availability change. People could return to their work without having to hold on to the same cluster for its entire lifetime.
Imagine pausing a large pretraining run to make room for a wave of smaller post-training experiments. The GPUs return to a shared pool; the saved training state remains. Later, the run resumes on a different set of machines, perhaps with more capacity, perhaps with less. Interruptions and changes of plan become things the system is designed to accommodate.
Making this flexibility dependable is the research challenge. A training run carries more than model weights: its optimizer, progress through data, and the state shared across workers all matter. Moving or resizing it requires the system to preserve a consistent point from which to continue and reorganize execution around the resources now available. Fault recovery also means deciding what to save, how often to save it, and how much work may need to be replayed.
We want these capabilities to become the foundation of a shared training service. Many people could pursue independent models and experiments over an evolving pool of hardware. Resources could follow changing needs, with isolation and predictable sharing, while each run retains its own continuity. Access to training would depend less on securing a fixed allocation from beginning to end.
Our ambition is to make pausing, resuming, moving, and resizing ordinary parts of training. This calls for the runtime, GPU execution, and network to work together, carrying the complexity of changing machines on behalf of the people using them. The future we are working toward is one where a training run can last as long as the work requires, and use hardware when and where it is available.